It was a great idea. Just not executed well.

1 Like

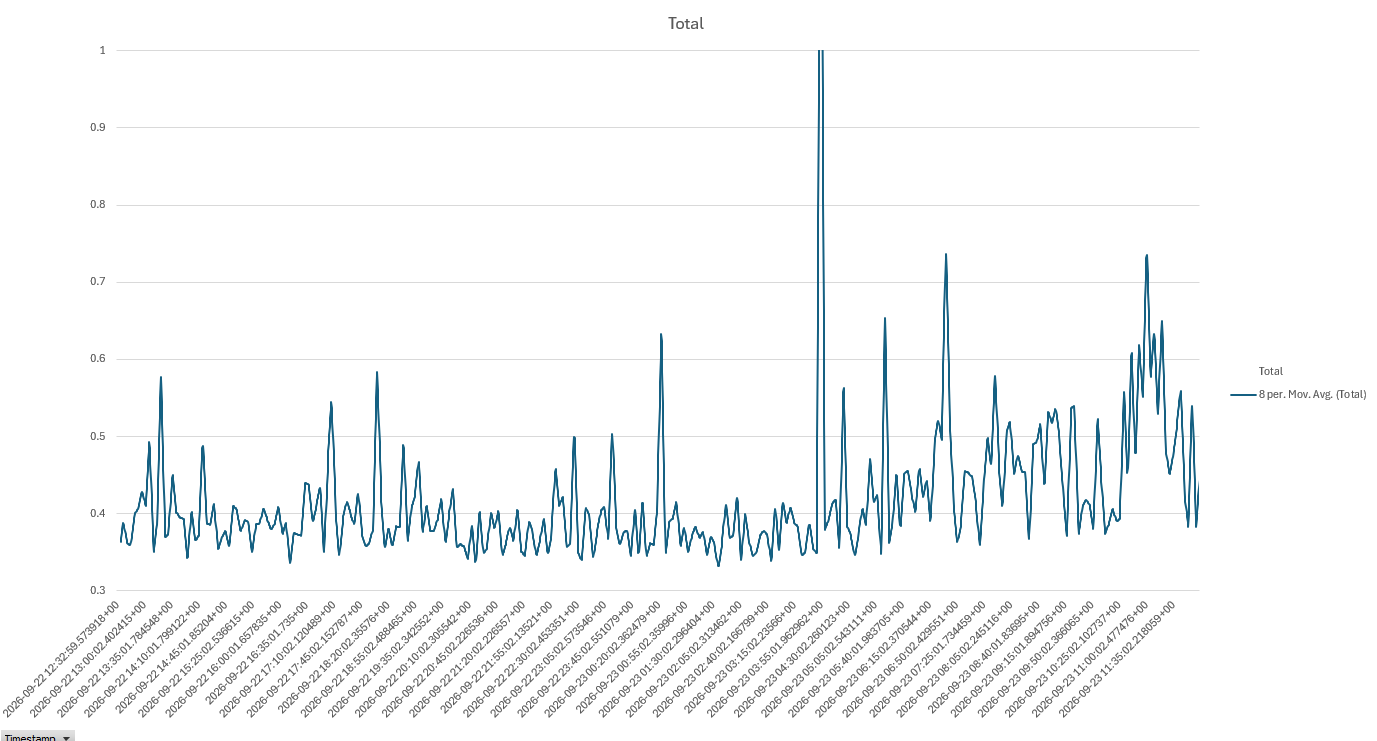
We’ll see who wins in the #inthesubset lottery tomorrow I guess.

I dont know about the rest of you, but this is honestly just a normal day for us. This is a constant thing. Feels less like a lottery and more like a coin flip.
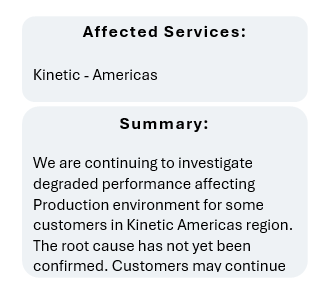
…and the second update today is a word-for-word match to the second update from 9/8/26.
The recurrency of these “degradations” is getting worrisome…not to mention the boilerplate emails that follow.
At least they didn’t bother sorting them to make finding yours easy without CTRL-F? 
To be fair anyone can find server and client endpoints in search engine results. epicorsaas.com/robots.txt doesn’t exist, so we’re indexed.
In the spirit of fixing the support ticket instead of the problem, they’ve been sticking robots.txt to individual client endpoints. Which would inform crawlers, if they navigate sequentially, which they’d need a bit of sitemap to do, normally pointed out in the root robots.txt, which doesn’t exist.
I thought it was funny that the email didn’t have the whole list, or at least it was weird that the email list ended with a comma making it seem like there were more companies on it.
We’re #inthesubset today. I take a little blame, because i got complaints at 9 am CST but felt i needed proof before i entered a case. I accumulated logs and i put the case in at 11 am cst as outage, and it still took 2 hours to get assigned.
Boilerplate is good. Having someone type up messages is error prone and wasteful. Nevertheless, look at the timing on iterated updates. Today’s range from 19 through 35 minutes apart. That’s not sending itself. An actual human is still clicking ‘send’ on boilerplate updates.
Any day now…

Anyone else in here that’s having BAQ problems after the original issue was resolved?
We’ve got the read-only DB copy in our environment and it’s not syncing with prod since around the resolution time. It’s causing our internal apps that pull data via BAQ to report out-of-date info.
It isn’t good when it’s the same statement over and over from week to week. Cut, paste, send. Maybe if the core issues were really fixed we wouldn’t see them anymore.
Entirely possible…our read-only went off the rails during an outage on 7/31…right in the middle of monthend. Finally got it fixed around midnight, had to manually rerun a bunch of scheduled tasks that use an ODBC connection to the R/O DB. Good times. Suggest opening an EpicCare case to have them verify/fix your sync.
There aren’t enough customers on here to make a difference. Only a small subset of customers are here and complain when it’s down. So Epicor just sees the same group of customers complaining. And it’s been wrote off as we all just like to complain about SaaS.
Epicor moves business disruption to the cloud. Er I meant Innovation. 
The cloud team seems to have gotten it fixed overnight, but we ended up marking about 90 BAQs with “Use Primary Database” just to get 3rd shift production going before we went to bed. Turns out that’s not something you can do via DMT. @ordazl is going to need a new mouse.
Eh, its a bigger subset of customers than you think. Lots of people here who havent made an account and just lurk. I was here for three years before I made an account.
Its more so that the people who’s opinions actually matter to them arent here, which is exec’s and the heads of companies.
We’re just admins and devs here, and lets be honest, its rare for anything admin/devs complain about to be taken seriously.
I was here for three years before I made an account
Same, I should have made an account sooner!