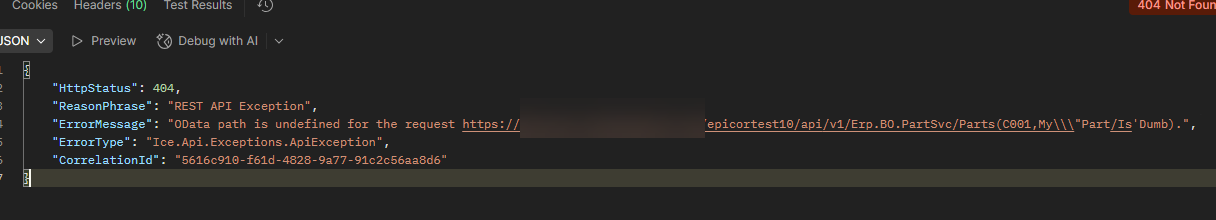
Following one of the recent minor updates I had to update some work to percent encode " to %22. Sending a percent encoded parentheses before the update failed, only literal parentheses matched. Meanwhile, # has always needed to be encoded as %23 for as long as I’m aware. I’m currently passing / over API V1 and V2 with great success.
It kinda looks like developers have been handwriting percent encoding one character at a time, ticket by ticket, applied SaaS client by SaaS client. Surely not though? Everything in the process has some kind of .urlencode(), some by default requiring manual intervention to disable it.
         proxy_pass https://myEpicor.stephengould.com;
         proxy_set_header X-Original-URI $request_uri;
    # Force nginx to use the normalized URI
         rewrite ^ $uri break;
Also gives an error if slashes are included
So… Im’ not sure what this proves other than yes if you configure the nginx Linux proxy (incorrectly) you can get it to pass in the decoded URI and it will cause Epicor to balk wiht a 400,500, and or a 404 Error.
It sounds like all their Linux NGINX Proxies are configured the same way since Evan is also seeing this. So I’m sure you will but they probably need to figure it out for everyone
Your live Windows Error was I believe because the URLEncode didn’t work in that SWAGGER version. If you call it in POSTMan it works (at least it did for me)
I reported this on my Live (windows) instance. They updated the proxy in anticipation of the Linux move, and that’s what’s causing the issue. So it’s Linux related, but by association (this is my guess - not confirmed).
I mean, he’s incredibly good-looking….so he’s got that going for him - which is nice
There are a ton of US-Central based customers, and since my guess is that this was in anticipation of the Linux move in Spring, splitting up maintenance could make sense??